AI Infrastructure
Clockwork Guarantees AI Training Won't Restart: New YOCO Contract Covers GPU Failures
A fault-tolerance software layer lets training jobs survive GPU and node failures by migrating to healthy hardware—without losing progress or recomputing work.

The New Stack
Training large language models on vast GPU clusters means expecting failure—but it doesn't have to mean restarting from an old checkpoint. Clockwork, which builds reliability software for AI training, is now backing that claim with a contractual guarantee.
The company introduced its YOCO Guarantee (short for "You Only Compute Once") on Wednesday, pledging that 90 percent of failures will be fixed without any loss of training progress. If Clockwork misses that target in a contract year, customers receive a 25 percent credit on renewal or expansion costs. The guarantee rests on TorchPass, Clockwork's fault-tolerance product that reached general availability in March.
Live Migration Instead of Rollback#
Today's typical approach to GPU failure is blunt: roll back to the last checkpoint (potentially hours old) and recompute everything since. That wasted GPU time costs real money—Clockwork estimates more than $6 million annually on a standard 2,048-GPU deployment.
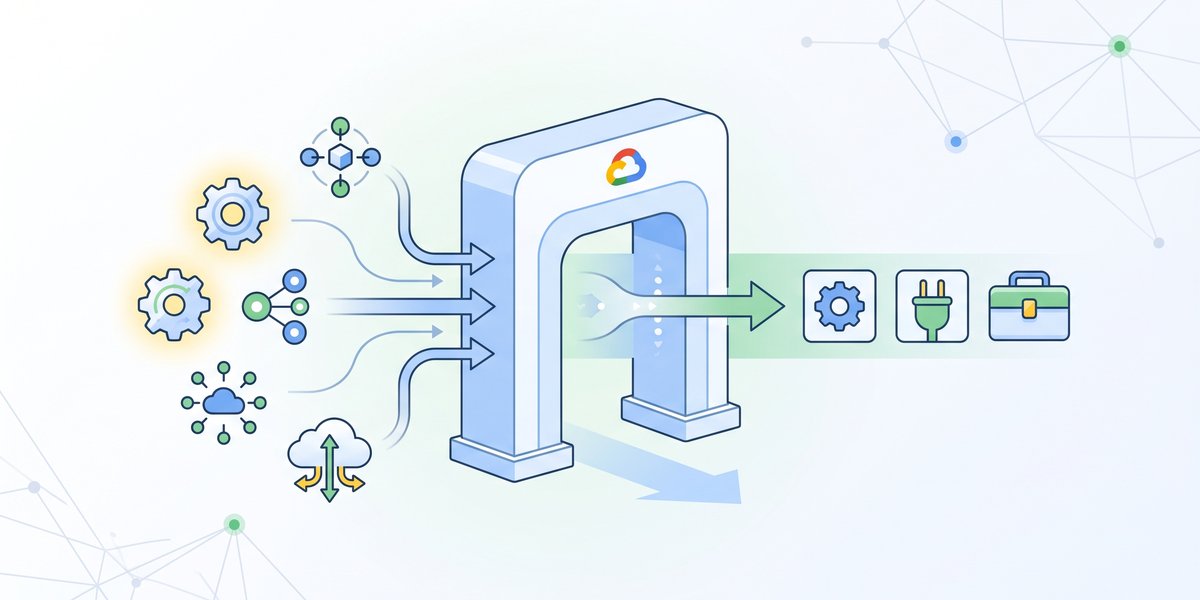
TorchPass sidesteps rollback entirely. When a GPU or node fails, it copies the job's live state—model weights, gradients, optimizer state—to a healthy replacement and resumes training at the next iteration, not the last saved checkpoint. Recovery typically takes just minutes with the model-transparent mode, or tens of seconds with a model-aware variant that requires minimal code changes.
The replacement GPU can come from a standby spare or be pulled from a lower-priority job, which TorchPass pauses and migrates elsewhere. Proactive migration is also possible: if a GPU's temperature spikes or other warning signs appear, TorchPass can move the job before failure strikes.
How It Works#
TorchPass operates in two modes. The model-aware approach requires just a few lines of extra code, letting TorchPass know precisely what state to migrate, reducing data transfer and recovery time to tens of seconds. The model-transparent mode needs no code changes—the system captures a hardware-level snapshot—but moves more data and takes a few minutes to restore.
For sudden crashes when a node dies before any snapshot can be taken, Clockwork rebuilds the lost worker's state from the healthy data-parallel replicas already running as part of normal distributed training.
Limitations exist. Network-wide outages or complete power loss leave no room for recovery. Failures also become increasingly frequent at scale: Meta's FAIR research (cited in Clockwork's announcement) shows mean time to failure drops from 7.9 hours on a 1,024-GPU cluster to 1.8 hours at 16,384 GPUs, causing clusters to run at only 30–50 percent of theoretical performance.