AI Infrastructure
Smart GPU Scheduling Boosts Cluster Efficiency by 33 Points Without New Hardware
A constraint-aware allocator that prioritizes job placement improved GPU utilization and output value significantly, proving that how work gets scheduled matters as much as the capacity available.

Hugging Face Blog
A constraint-aware GPU scheduler demonstrated dramatic efficiency gains on identical hardware by reordering how allocation decisions are made. Testing across seven scenarios showed GPU utilization jumping as high as 33 percentage points and priority-weighted output rising by up to 105%—all without adding a single new device.
The core insight: which GPU runs which job, in what order, matters far more than total capacity when clusters face real contention.
The Problem with FIFO Scheduling#
Traditional first-in-first-out (FIFO) schedulers treat all workloads the same, placing jobs as they arrive regardless of priority or how efficiently that placement uses space. In practice, this creates two distinct penalties.
Reservation waste: Real-time inference services need immediate access to GPUs when traffic spikes, which forces administrators to reserve hardware for peak demand throughout the entire day. An application needing six GPUs at midday but only two at 4am ties up four idle units for 20 hours straight. This idle-but-reserved capacity becomes invisible lost throughput—the cluster reads as having capacity when it does not.
Placement inflexibility: FIFO commits GPUs to whichever job asks first, leaving later-arriving work without suitable contiguous blocks. High-priority jobs wait behind low-value requests; capacity gets fragmented in ways remaining jobs cannot use. Under contention, the order you place jobs becomes the capacity decision.
The two problems compound: real-time reservations consume half the pool in mixed workloads, and whatever remains gets handed out in arrival order.
How the Allocator Works Differently#
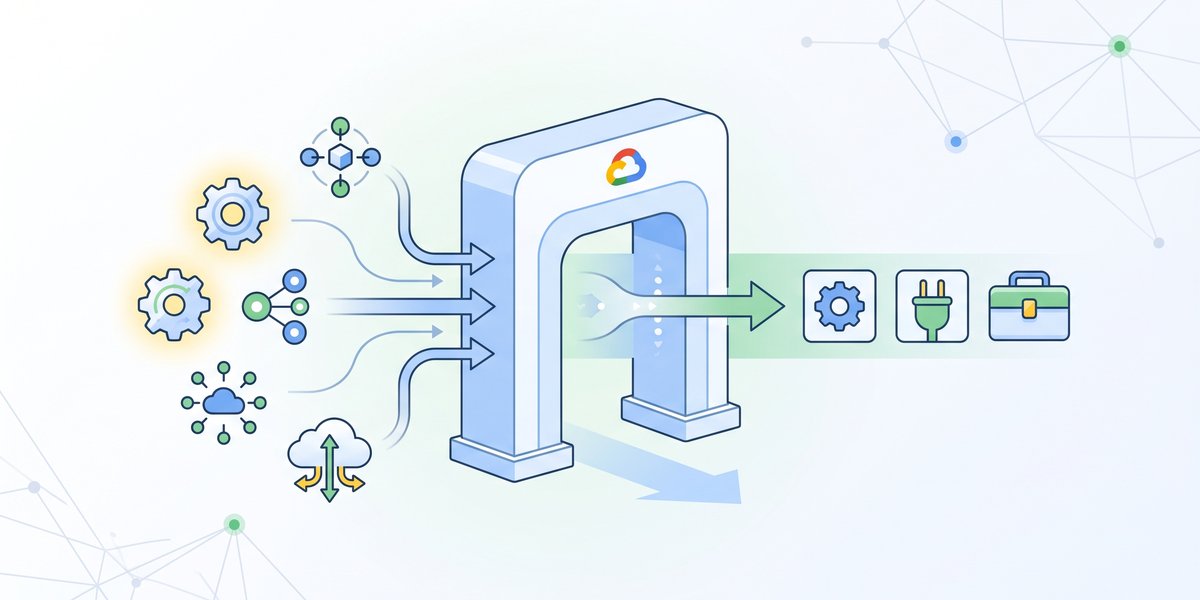
The new scheduler treats real-time demand as a demand curve rather than a fixed ceiling, allocating GPUs per timestep based on actual traffic with a swap-cost cap. Batch jobs—training, batch inference, and quantization—are placed by priority across the entire scheduling horizon instead of by arrival order.
The system runs with five structural constraints:
- Each GPU serves one job per timestep
- Jobs respect their demand range; running work is inherited
- Batch jobs occupy contiguous GPU blocks sized to powers of two
- Real-time jobs have a hard cap on GPU-swapping between timesteps
- Started jobs cannot be interrupted
The objective function uses two weighted terms: rewards for allocating GPUs to batch work (scaled by priority and time decay), and penalties for unmet real-time demand. The penalty is 5–10 times heavier, which means latency obligations get enforced the same optimization as batch placement, rather than by a separate autoscaler fighting the scheduler.