AI Hardware
OpenAI's custom Jalapeño chip shows 1.5–4× faster inference through AI-optimized kernels
Early benchmarks reveal how OpenAI's nine-month-old inference accelerator balances throughput and latency for interactive AI agents—and how AI itself rewrote its own code.

The New Stack
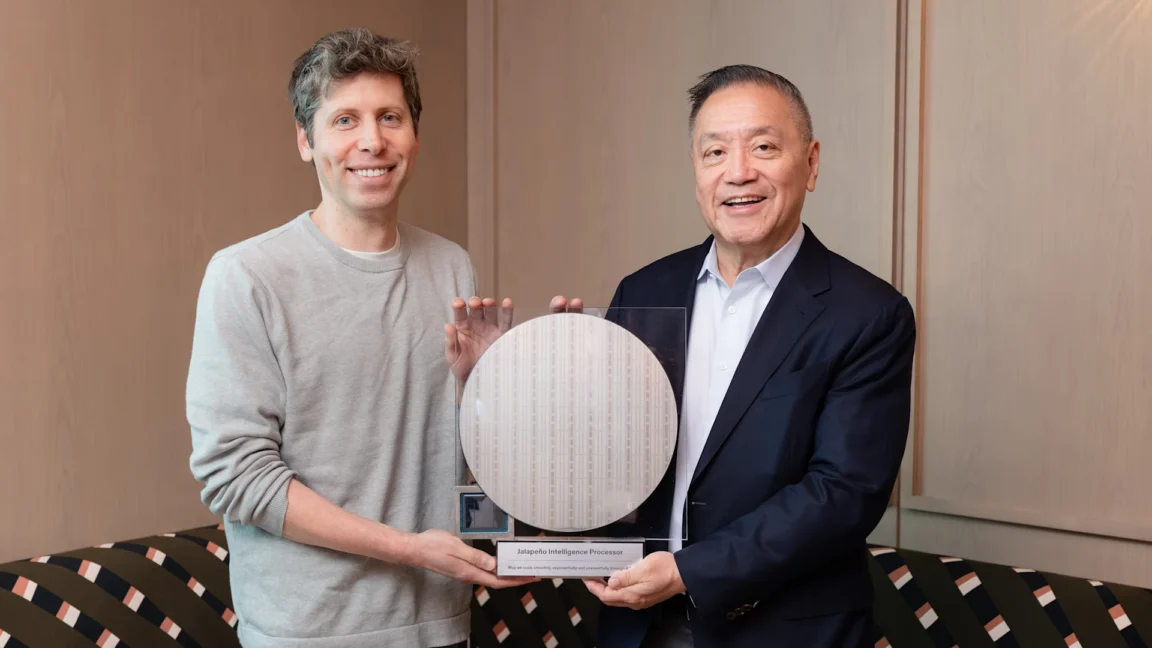
OpenAI's first custom inference chip, Jalapeño, developed with Broadcom, has now published performance results that back up its June launch claims. Testing across three large language models shows the chip delivers between 1.5 and 1.9 times more work per watt while reducing end-to-end latency by 1.7 to 3.6 times compared to existing accelerators—and up to 4.1 times faster on highly interactive workloads.
The results underscore a core design philosophy: inference chips often optimize for either speed or efficiency, but Jalapeño targets both.
Why latency matters for AI agents#
Unlike single-prompt use cases, AI agents that complete multi-step tasks invoke models repeatedly, making small delays compound into significant overhead. Each inference cycle—tool calls, decisions, state updates—can accumulate milliseconds into perceptible slowdowns across an entire workflow.
Jalapeño was engineered to address this. The chip reduces the time data spends moving between compute and memory subsystems. Large language models place different demands on hardware at different stages: the initial prompt processing is compute-intensive, while token generation demands higher memory bandwidth. Jalapeño keeps the model state and key-value cache local, minimizing data shuffling as the workload shifts between these phases.
Benchmarks show the tradeoffs#
OpenAI ran Jalapeño through InferenceX, SemiAnalysis' inference benchmark, using GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T. Power-efficiency comparisons, based on published accelerator ratings, showed particularly striking gains when Jalapeño operated at previous best latency points: between 8.6 and 104.3 times more work per watt depending on the model. The chip is rated at 700 watts but never exceeded 550 watts during testing.
This matters because the traditional speed-versus-efficiency tradeoff—batching more requests to boost throughput while accepting longer per-request delays—no longer suits OpenAI's economics. The company continues reducing API costs while needing interactive applications to remain responsive, making balanced performance essential.
AI-generated code outperformed human engineers#
Perhaps unexpectedly, OpenAI used its own models to accelerate Jalapeño's development, compressing the design-to-silicon timeline to nine months. The surprises didn't end there: AI-generated implementations of attention and mixture-of-experts kernels ran 1.5 to 1.8 times faster than hand-written versions by OpenAI's own hardware experts.