AI Infrastructure
Slack's Multi-Cloud AI Playbook: From SageMaker to Multi-Provider Resilience
Slack engineered a four-phase migration to multi-cloud AI serving, combining AWS Bedrock and Google Cloud Vertex AI to boost complex reasoning accuracy by 10% while slashing short-prompt latency by two-thirds.

InfoQ
Slack has detailed its evolution toward multi-cloud AI infrastructure, tracing four stages of architectural refinement that moved the company from managing its own SageMaker clusters to orchestrating workloads across competing cloud providers.
The journey reflects a broader shift in enterprise AI operations: as teams scale AI features to millions of users, single-vendor lock-in becomes a liability. Traffic swings of 10× between peaks and off-hours, capacity constraints on premium GPUs, and limited model access all pushed Slack toward a more resilient approach.
The Four-Phase Evolution#
Phase 1: Self-Managed SageMaker. Slack's initial setup ran in an isolated escrow VPC with dedicated A100 and H100 GPUs, requiring manual capacity forecasting and advance planning—a heavy operational tax that risked customer-facing outages.
Phase 2: Amazon Bedrock. Offloading GPU management to Bedrock's managed service reduced operational burden and accelerated access to newer Anthropic models. The company migrated via feature flags and load testing without incident.
Phase 3: Hybrid Capacity. To handle 10× traffic swings, Slack combined Bedrock's Provisioned Throughput for interactive traffic with On-Demand capacity for bursty workloads, balancing cost and latency.
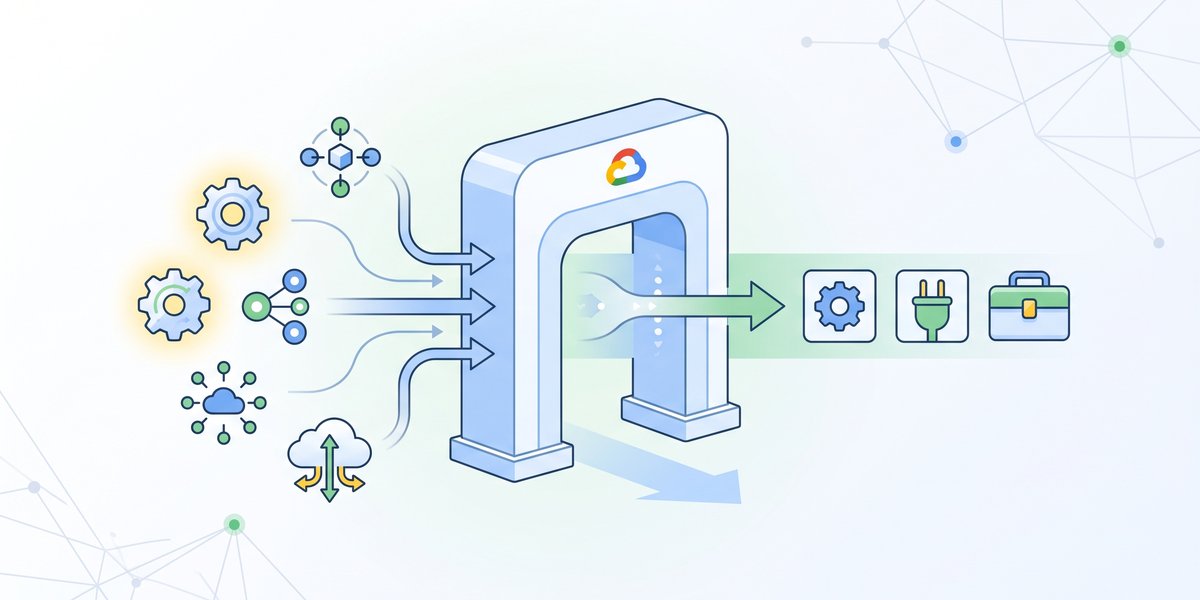
Phase 4: Multi-Cloud Abstraction. The final step introduced a provider-agnostic serving layer that normalizes APIs across AWS Bedrock and Google Cloud Vertex AI. Intelligent routing continuously evaluates metrics like time-to-first-token and p90 latency, redirecting traffic away from degraded endpoints. The abstraction layer also enables A/B testing and controlled model rollouts.
Results#
The multi-cloud setup improved reasoning accuracy by ~10% on complex tasks and slashed latency on short prompts by ~67%. Beyond those metrics, Slack gained access to a broader model portfolio, better geographic failover, and freedom from any single provider's limitations.
Broader Industry Momentum#
Slack is not alone. Companies like Padiso route Claude traffic across Bedrock, Vertex AI, and Anthropic's direct API to manage failover and provider risk. BentoML advocates similar cross-cloud strategies to optimize for latency and availability. For platform teams, the lesson is clear: abstraction layers that decouple application logic from model providers unlock portability and resilience—prerequisites for scaling AI in production.