AI Infrastructure
GPU Utilization Is Becoming AI's Biggest Economic Constraint
As enterprises buy their own hardware, managing idle time and workload allocation on GPUs has emerged as a critical discipline separate from—and as important as—the models themselves.

Hugging Face Blog
The economics of AI infrastructure mirror a lesson aviation learned decades ago: cost matters far less than how intensively you use your equipment. Just as an aircraft depreciates and burns fuel whether it flies or sits idle, a GPU accumulates charges for power, cooling, and financing regardless of whether it's processing useful work. For enterprise AI teams, this shift is creating a new operational bottleneck.
Why Capacity Purchasing Solves Nothing#
When companies made the arithmetic shift from paying per API call to buying their own GPU clusters, they traded a scalable cost for a fixed capital commitment. Below a certain usage threshold, the math favors APIs. Above it, owning hardware wins. But ownership itself doesn't close the problem—it opens a harder one.
A GPU cluster sits idle much of the time. Demand peaks and valleys throughout the day and week, but infrastructure must be sized for peak load, which means substantial unused capacity during normal operations. The real problem compounds this: not all GPUs are equally suited for all tasks. A modern cluster might run inference, fine-tuning, training, quantization, and embedding generation simultaneously. A GPU optimized for low-latency inference performs poorly for batch processing; hardware shaped for real-time requests can't efficiently handle background jobs queued for hours. A system can show high average utilization while simultaneously having jobs waiting in queues for GPU shapes that happen to be occupied running lower-priority work.
This is where the aircraft analogy breaks down and reveals something deeper. An idle 737 in Chicago can fly to Denver or Dallas interchangeably. An idle GPU cannot absorb just any workload—it must match the memory, latency, and duration profile of the job waiting for it. That constraint makes orchestration harder than simple scheduling.
The Emerging Discipline of GPU Management#
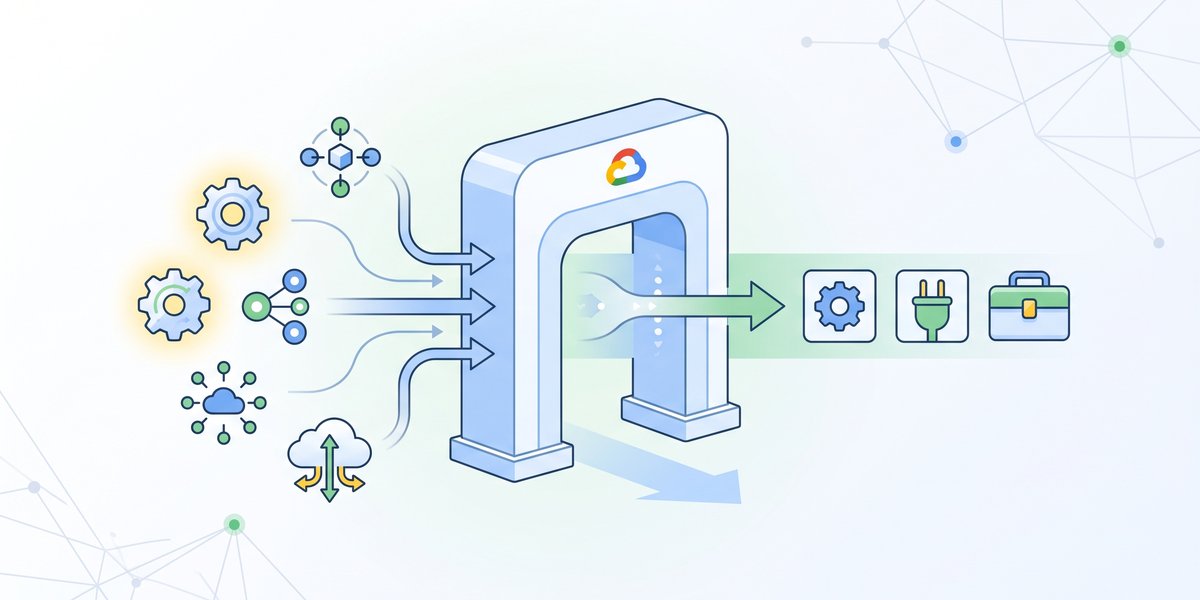
What's crystallizing in response is GPU Management: a formal orchestration layer sitting between workloads and hardware, making continuous allocation decisions in real time. This isn't a procurement problem solved once at purchase time; it's an operational problem that unfolds every hour, every time a job completes and another waits for resources.
The discipline calls for:
- Real-time allocation: deciding which workload runs next on hardware that just freed up
- Priority arbitration: balancing customer-facing services against internal training runs, batch jobs against real-time requests